Overwhelmed by AI Bots

I've tried to analyze AI bots coming to this self-hosted blog. I wanted a simple guideline for admins to follow so we can separate AI bots from other bots and users.
I give up. There are too many, changing too frequently and there’s no fixed point to hold on to. Here’s the Marimo notebook that’s WIP, probably will never be finished. By the time I fix one section, another one is outdated.
As I spent way too much time on this, I'm just seeking closure with something positive. So here are my notes:
- 8% potential AI bot traffic (includes impostors), approx. 20 requests per hour,
- Cloudflare Radar: great intel source, but incomplete and fickle,
- User Agents are annoying to work with - only check simple substring as robots.txt does,
- Upcoming JSON standard for bot IP ranges declaration,
- HTTP Messages Signature RFC9421,
- Petalbot / Huawei / Deepseek relation,
- JA4 didn’t help.
Next time I'll try Fingerprint.js or Anubis. Rate-limiting works well in the meantime.
Let's dig in.
Overall Traffic
Taking a look it seems I have approximately 8% of potential AI traffic (user agent is in the list of AI bots as per Cloudflare Radar). Here’s the breakdown of that 8%:
Keep in mind that this includes impostors - especially Googlebot is commonly impersonated and I think that’s the reason for it’s majority. In the separate Google article, I’ve counted that valid Google traffic is an order of magnitude less than trash from GCP.
I’m happy to report that this volume is of no concern to my humble site. Even with this potential number, that’s about 20 requests per hour.
General AI Bot Categories
There are three general categories of the AI bots with some differences in intent:
- AI Crawler: The bots gathering data for training of models.
- AI Assistant: A human instructed AI agent to directly fetch something relevant for its queries.
- AI Search: A human instructed AI to search for anything relevant and it found your site.
Most companies use these categories of bots for these exact purposes.
An outsider has no way of verifying any of this, we have to trust the declared intent. And it’s hard to, especially when reputable sources like Cloudflare claim that even bots like Googlebot (crawling for search engine purposes) feeds data into AI training.
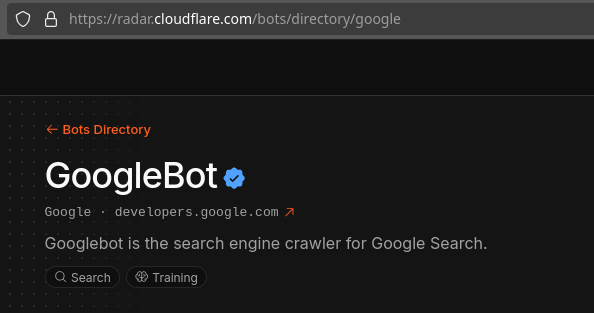
Speaking of the devil...
Cloudflare Radar Is Fickle
Everybody knows (TM) that Cloudflare is the creme de la creme of bot detection. And they publish a lot for free too in Cloudflare Radar! I wanted to base most of the conclusion on their data, because it’s a one-stop-shop.
Then I’ve found this “mirror” of Cloudflare Radar on GitHub, which seemed like the perfect baseline for bot intelligence.
Unfortunately, we’re missing the IP ranges and I’ve observed the bots are dropping out of the index randomly. For example, the Amzn-User bot got lost somewhere, even though official docs still list it (as of 17th November 2026). Same story with Kimi-User.
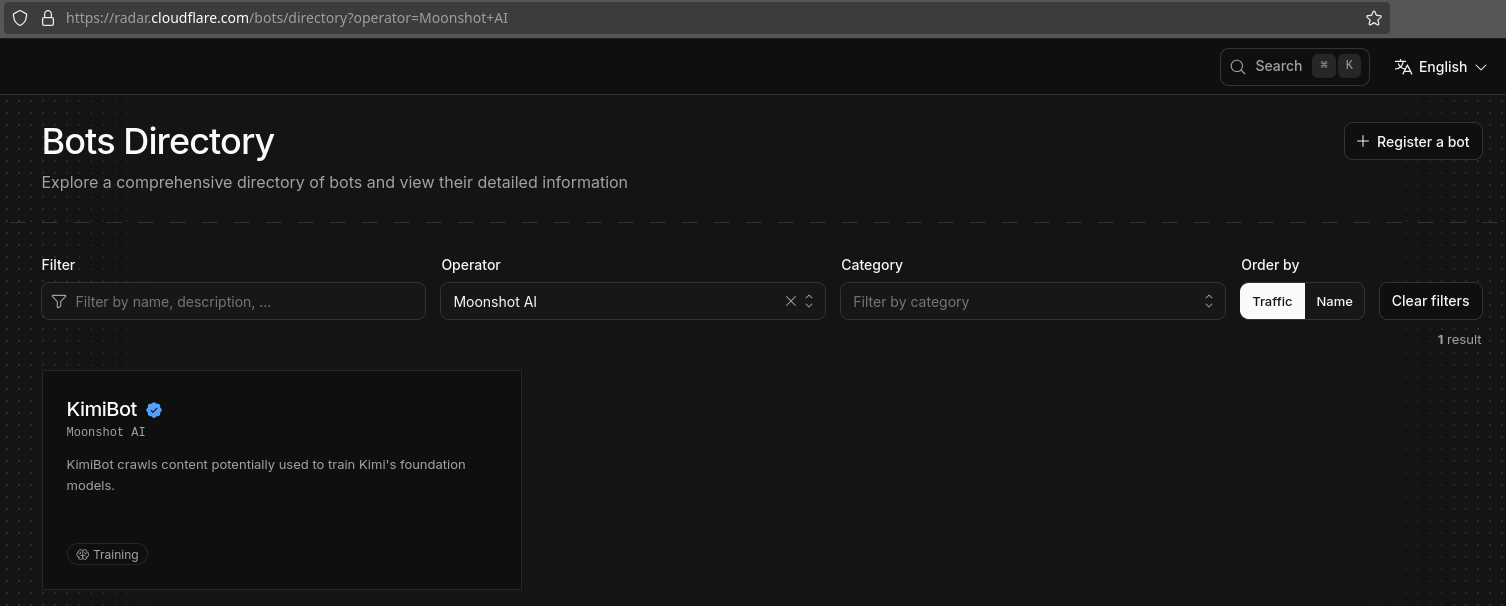
Of course, it’s a live intelligence feed so it changes in time. The format can change without prior warning and that’s fine. It’s still unpleasant though.
Look I get it. It’s very hard to monitor so many bot swarms (as I’ve learned), to keep all this intelligence up-to-date. Especially when the bots in question have no motive for cooperating. For starters, you have to observe an enormous amount of traffic and that’s a feat in an of itself.
Cloudflare Radar Alternatives
When getting intelligence alternatives, you usually see two issues. It's either expensive or incomplete.
Here are some incomplete overviews (just search for Kimi or Instapaper - I didn't find it):
- Fingerprint - Also an OpenSource Javascript based fingerprinting solution!
- Menoro
- LightSite
- Allmo
- CrawlerIndex
I'm not paying for this, so I can't recommend paid sources. I'm confident there are people happy to take your money in exchange for such intel. I saw LLMPulse, but they admit (as of 18th November 2026) they base this on Cloudflare Radar data.
So YMMV, I conclude that Cloudflare Radar is the best. I might be very wrong about this.
RFCs And Standards
Maybe the real treasure were standards I’ve encountered along the way. Because I’m sure I’ll see them again someday soon.
User Agents
I hate parsing user agents. The standard is non-existent, the best I’ve found is this section in RFC9110 and that’s clearly not enough.
It’s infuriating because you see two user agents that are of the same origin, but handling all of the nonsense in code is just too much work.
Robots.txt RFC9309 also agrees - the rule is if a substring is present, then the user-agent matches, e.g. GPTBot matches Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot). No more, no less, deal with it.
Published Bot IP Addresses Format RFC?
There also seems to be an emerging standard on declaring IP ranges for bot operators, so I'm happy to parse all such files.
It’s quite simple, it’s a JSON like:
{
  "creationTime": "2026-09-22T02:00:07.000000",
  "prefixes": [
    {
      "ipv4Prefix": "132.196.86.0/24"
    },
    {
      "ipv4Prefix": "172.182.202.0/25"
    },
    {
      "ipv4Prefix": "172.182.207.0/25"
    },
    ]
}
Parsing left as an exercise for the reader, but it’s present in the WIP notebook. Bonus points for using binary trees for subnets!
I was surprised to see that AWS botched this. The lists of IPs (here, here and here) are wrapped in a lot of weird HTML, but that's nothing a simple scrape cannot solve. The prefixes are also not CIDR subnets but static IPs and there's a "ipv4prefix" vs "ip_prefix" inconsistency... AWS, you were good at this! Do better!
HTTP Messages Signature RFC9421
RFC9421 was published in Feb 2024. The general idea is that a bot would have a JWT that’s verifiable against published keys. The JWT also contains the “scope” of the bot action (random request parameters) so that we’re able to constraint bot activities.
I think this is promising tech - if this would get widespread adoption, then you could whitelist good bots by accepting their keys. JWT is pretty standard so it’s well supported and simple to understand. How exactly we’ll get the keys is an interesting but separate problem as noted in the RFC.
Petalbot / Huawei / DeepSeek?
Apparently, Huawei operates it's own search engine. Naturally, they need to get some data for indexes. Not sure why it's in the AI crawler category, the only thing I've found is that Huawei and DeepSeek are joining forces. So maybe this humble bot is a part of that deal.
We're lacking the common user and search subbots. It's also different in the sense that they do not provide an IP list, but instead every IP that has a reverse DNS that includes petalbot is official. That’s a radical choice, but I respect it. Couple more bots use the same approach, so it's worth keeping that in mind.
JA4 Didn’t Help Me
I was trying to avoid this, but I can’t. I don’t say it doesn’t work, I’m saying that it was a much weaker signal than expected. I’m not confident in any of these correlations. The bots are grouped randomly, one bot has multiple hashes, these might change over time as versions are upgraded.
I really wanted to avoid JavaScript based fingerprinting and behavioural analysis, but it seems to be the way. I might re-visit these later.
Fall Back And Regroup
Gathering and keeping this intelligence up-to-date is more than I wish to do in my spare time. In the meantime, the internet was shook with vulnerabilities like PHP2Shell and other 2Shells. There were also some outages and serious cyberattacks. I’m not affected at all today, but tomorrow might be different.
Fortunately my site is robust enough that these AI bots are an ignorable noise. I have my reservations about giving my organic thoughts into the next round of trainings, but that’s a lower priority problem right now.
Better solutions do exist - I'll be trying them in the future. I have my eyes on Fingerprint.js and Anubis. Basic rate-limiting is doing a lot of the heavy lifting in the meantime.
I have to admit, maybe I was a little bit too arrogant trying to take on these huge companies by myself from first principles.